## Product Documentation
### PDF API Toolkit Container | Enterprise PDF Processing | Datalogics
**URL:** https://www.datalogics.com/pdf-api-container-enterprise
Datalogics API Toolkit Container delivers every PDF processing tool you need, built by Datalogics' digital document experts.
### Datalogics PDF Container | Docker & Kubernetes PDF API
**URL:** https://www.datalogics.com/pdf-software-container
Datalogics API Toolkit Container delivers every PDF processing tool you need, built by Datalogics' digital document experts.
### callas Preflighting & PDF/A Software - Datalogics
**URL:** https://www.datalogics.com/callas-pdf-software-tools
Datalogics offers preflighting and PDF/A capabilities within Adobe® Acrobat Professional via our partnership with callas software.
### Adobe PDF Print Engine | RIP SDK for Commercial & Industrial Print
**URL:** https://www.datalogics.com/adobe-print-engine
Build high-performance RIP technology with Adobe PDF Print Engine. The industry-leading rendering SDK for packaging, label, textile, and industrial print applications.
### Adobe PDF Library SDK | Built on Acrobat's Engine | Free Trial
**URL:** https://www.datalogics.com/adobe-pdf-library
A powerful SDK (Software Development Kit) designed for developers to build applications that can create, manipulate, render, and print PDF documents. Based on the same core technology as Adobe Acrobat, it provides a comprehensive set of functions for handling PDFs without relying on Adobe Acrobat or Reader.
### Adobe InDesign Server License & Support | Datalogics
**URL:** https://www.datalogics.com/adobe-indesign-server
See licensing and pricing levels for InDesign Server to automate your publishing process.
### Adobe PDF Library for Maven | Datalogics
**URL:** https://www.datalogics.com/adobe-pdf-library-maven
Process PDFs with Adobe PDF Library for Maven
### Adobe PDF Library .NET Framework | PDF Processing with NuGet | Datalogics
**URL:** https://www.datalogics.com/adobe-pdf-library-nuget-dotnet-framework
Adobe PDF Library is the industry's most comprehensive PDF SDK, built for enterprise-scale creation, editing, and document management, and trusted by leading organizations and SaaS providers worldwide.
### Adobe PDF Library for .NET | NuGet | Datalogics
**URL:** https://www.datalogics.com/adobe-pdf-library-nuget
Everything you need to add Adobe's PDF engine to a .NET project through NuGet.
### Render, Flatten & Convert XFA and AcroForms without Acrobat
**URL:** https://www.datalogics.com/pdf-form-functions
Forms Extension is an SDK add-on for the Adobe PDF Library that adds full programmatic support for AcroForms and static and dynamic XFA. It renders, flattens, converts, and extracts form data in server environments without Adobe Acrobat.
### Adobe PDF Converter - Convert EPS and PS to PDF
**URL:** https://www.datalogics.com/convert-eps-to-pdf
Convert PostScript, EPS, PPML, and images to PDF with full developer control. Parallel processing, page-level streaming, PDF/X-4, and ICC color management. Free trial available.
## Technical Articles
### XFA Forms Are Deprecated: What It Means for Your Workflow
**URL:** https://www.datalogics.com/xfa-form-deprecation
XFA was deprecated in PDF 2.0 and is no longer supported in Chrome, Firefox, mobile viewers, or PDF/A. Here are your three options for dealing with legacy XFA forms in your workflow.
If your organization uses PDF forms, there is a reasonable chance some of them are XFA forms. XFA (XML Forms Architecture) was the dominant format for complex, data-driven PDF forms for over a decade, used extensively in Adobe LiveCycle Designer and embedded in thousands of enterprise document workflows across government, healthcare, financial services, and insurance.
There is also a good chance those forms are causing problems you may not have fully diagnosed yet.
XFA was officially deprecated in the PDF 2.0 specification. The format is no longer supported in the most common PDF viewers, is prohibited in archival PDF standards, and is creating a growing compatibility backlog for organizations that have not yet addressed it. This post explains what XFA deprecation actually means and what your options are.
## What Is XFA?
XFA stands for XML Forms Architecture. It is a form technology developed by Adobe that embeds XML-based form logic and layout instructions inside a PDF file. Unlike AcroForms -- the standard PDF interactive form format -- XFA forms contain their own rendering engine. They describe how the form should look and behave using XML rather than relying on the PDF page structure.
This made XFA useful for dynamic forms: documents that could expand or contract based on user input, show or hide fields conditionally, and perform calculations that a standard AcroForm could not easily handle. It was widely adopted in industries with complex, data-heavy forms: government benefit applications, financial loan packets, healthcare intake systems.
## What Does "Deprecated" Mean?
The PDF 2.0 specification (ISO 32000-2:2017), published in 2017, formally deprecated XFA. Deprecation in a specification means the technology has been officially removed from the standard. It is no longer part of what a compliant PDF should contain.
In practical terms, this means PDF viewers and tools built to the PDF 2.0 standard are not required to support XFA -- and most modern ones do not. Adobe Acrobat continues to render XFA because Adobe created the format and maintains backward compatibility. But Acrobat is now the only widely used PDF application that does.
## Where XFA Forms Break Today
- **Google Chrome's built-in PDF viewer** does not support XFA. When users open an XFA form in Chrome, they may see a blank page, a partial rendering, or a message asking them to open the file in a different viewer.
- **Mozilla Firefox** does not support XFA. Same result as Chrome.
- **iOS and Android PDF viewers**, including Apple Books and most third-party mobile apps, do not support XFA.
- **PDF/A**, the ISO standard for archival PDFs, explicitly prohibits XFA. If your document management or archiving system validates against PDF/A, XFA forms will fail that validation.
- **PDF/UA**, the accessibility standard for PDF, does not support XFA.
- **Many document ingestion platforms, printing systems, and workflow automation tools** either reject XFA or produce incorrect output when they encounter it.
The result: users who receive or open XFA forms in anything other than full Adobe Acrobat will encounter problems. In a world where document review and form submission increasingly happens in browsers, mobile devices, and integrated document platforms, that covers a significant share of your audience.
## Three Paths Forward for Legacy XFA Forms
### Option 1: Do Nothing
This is the path of least resistance and the highest long-term risk. XFA forms will continue to work for users who open them in Acrobat. For everyone else, the problems will persist and likely grow as infrastructure upgrades and viewer updates move organizations further from Acrobat as the default PDF tool.
If your XFA forms are in a closed system where you control the entire viewer environment and all users have Acrobat, doing nothing may be acceptable in the short term. For any form that touches external users, public-facing systems, or archiving pipelines, it is not a viable long-term strategy.
### Option 2: Flatten to Static PDF
Flattening converts the XFA form to a static PDF. The form fields are removed and the data -- if the form was already completed -- is preserved as permanent page content. The output is a standard, universally compatible PDF with no XFA dependency.
This is the right path for forms that have already been completed and submitted. Archive documents, historical records, processed applications, signed forms: flatten them to static PDFs that will open correctly in any viewer, meet PDF/A requirements, and remove the XFA dependency permanently.
For high-volume batch processing of legacy XFA archives, a command-line tool like PDF Forms Flattener handles this at scale. You can process entire directories of XFA forms without Acrobat on the server.
### Option 3: Convert XFA Fields to AcroForm
If the forms are still in active use and you need to preserve interactivity -- users still need to fill them in -- flattening is not the right answer. Instead...
### SDK or API? Choosing Between Adobe PDF Library and the pdfRest Container for Your PDF Workflow
**URL:** https://www.datalogics.com/pdf-sdk-vs-api
A side-by-side breakdown of Adobe PDF Library and the pdfRest API Toolkit Container — two ways to access Datalogics' PDF processing technology. Learn how the native SDK compares to the self-hosted REST API, and which one fits your architecture, compliance requirements, and team's tech stack.
If your application needs to do anything beyond display a PDF, for example convert it, redact it, sign it, flatten a form, or pull structured text out of it, you eventually run into a decision: do you embed a PDF engine directly into your codebase, or do you call a PDF service over the network?
Datalogics offers a well-known answer to both sides of that question. Adobe PDF Library (APDFL) is a native SDK built on the same engine that powers Adobe Acrobat. The pdfRest API Toolkit Container is a self-hosted, containerized REST API for PDF processing. They come from the same company, share the same PDF-processing DNA, and perhaps surprisingly aren't really competitors so much as two different doors into the same house.
This post breaks down what each product actually is, where they diverge, and how to decide which one (or both) belongs in your stack.
## Quick Side-by-Side Comparison
| | **pdfRest API Toolkit Container** | **Adobe PDF Library** |
|---|---|---|
| Form factor | Self-hosted REST API (Docker container) | Native SDK (compiled/linked into your app) |
| Language support | Any language that can make HTTP requests | C++ (Modern & Adobe C/C++), .NET, .NET Framework, Java |
| Platforms | Docker/Kubernetes — on-premises, private cloud (AWS, Azure, GCP), or hybrid | Windows, Linux, macOS |
| Core engine | Datalogics PDF processing engine, containerized | Adobe's own Acrobat engine |
| Data residency | Makes no external calls; documents never leave your environment | Runs locally within your app's process/environment |
| Compliance | Positioned to satisfy HIPAA, GDPR, SOC 2 Type 2, and FedRAMP requirements | SOC 2 Type 2 certified; compliance standards support for PDF/A, PDF/X, ZUGFeRD, Factur-X |
| Feature range | Convert, compress, merge/split, OCR, redact, sign, forms, watermark, AI-oriented tools (summarize, translate, PDF-to-Markdown, TDM-reserve) | Create/modify, convert, OCR, text extraction & regex search, digital signatures, forms, image processing, optimization, compliance standards |
| OEM / redistribution | Supported — embed the container in your own product and redistribute under your brand | Supported — OEM, SaaS, or end-user licensing models |
| Pricing | Custom, based on usage (multi-environment, capacity-based, multi-year terms available); contact sales to scope | Custom, based on usage (OEM, SaaS, or internal/end-user licensing models); contact sales to scope |
| Free trial | Available via activation key + Docker Compose/Kubernetes deployment | Available with full, unrestricted SDK access |
| Best suited for | Teams wanting a self-hosted PDF API, full data control, and enterprise-grade licensing without writing PDF logic themselves | Teams embedding deep, custom PDF functionality directly into a C++/.NET/Java application |
## What Is Adobe PDF Library?
Adobe PDF Library (APDFL) is a developer SDK, not a web service. You link it into your application and call its API directly from your own code, in C++ (both "Modern C++" and the original Adobe C/C++), .NET, .NET Framework, or Java. It runs on Windows, Linux, and macOS, and is distributed through NuGet, Maven, or direct download.
The headline feature is that it's built on Adobe's own source code — the same core rendering and processing engine used inside Acrobat itself. That matters most at the edges of the PDF spec: complex color spaces, embedded fonts, XFA forms, layered transparency, and digital signatures are exactly where third-party re-implementations of the PDF spec tend to diverge from how Acrobat actually behaves. Because APDFL shares Acrobat's codebase, it handles those cases the same way Acrobat would.
Functionally, APDFL covers a lot of ground:
- **Creation and editing** — building PDFs from scratch, annotating, merging, splitting, flattening, bookmarks, layers, watermarks
- **Conversion** — to and from Word, Excel, PowerPoint, PDF/A, PDF/X, ZUGFeRD/Factur-X, EPS, PS, XPS, and images
- **OCR** — powered by Tesseract, with a newer OCR engine and plugin architecture
- **Text handling** — region- and pattern-based extraction, regex search, Unicode and CJK support
- **Security** — PAdES, CMS, and RFC 3161 digital signatures, encryption, redaction, and permissions
- **Forms** — AcroForms and XFA import/export, flattening, and XFA-to-AcroForm conversion
- **Compliance** — PDF/A, PDF/X, and e-invoicing standards like ZUGFeRD and Factur-X
Datalogics backs this with direct engineering support and a reported 90%+ customer retention rate, and APDFL is SOC 2 Type 2 certified. Its customer list — Boeing, IBM, Oracle, SAP, Chase, Fidelity — points at a specific kind of buyer: enterprises and OEMs where a rendering discrepancy in production is not an acceptable outcome.
Pricing is often custom, based on usage, and licensing terms differ depending on whether you're embedding APDFL into a product for external distribution (OEM), running it as part of an externally accessible service (SaaS), or deploying it for internal use only (which ...
### Factur-X: Is Your Business Ready for 2026?
**URL:** https://www.datalogics.com/factur-x-is-your-business-ready
France's e-invoicing mandate takes effect in September 2026. Here's what Factur-X is, how it compares to ZUGFeRD, and how to build compliant PDFs with Adobe PDF Library.
Businesses in France are running out of runway. Starting **September 1, 2026**, large and mid-sized companies must be able to issue and receive structured e-invoices — and every VAT-registered business in France, regardless of size, must be able to *receive* them from that same date. If you issue or process invoices for customers in France, or you're building PDF tools for the ERPs and accounting platforms they rely on, the format at the center of that mandate is one you need to know well: **Factur-X**.
If that name sounds familiar, it's because Factur-X and Germany's ZUGFeRD standard are, technically, the same format. Here's what that means for your business, and how to build Factur-X-compliant PDFs with the Adobe PDF Library.
## What Is Factur-X?
Factur-X is a hybrid electronic invoice format that pairs a human-readable PDF with a machine-readable XML file inside a single PDF/A-3 document. Open a Factur-X invoice in any PDF viewer and it looks like an ordinary invoice. But embedded inside that same file is a structured XML dataset — invoice number, seller and buyer identification, line items, tax breakdowns, payment terms — that accounting and ERP software can extract automatically, with no OCR and no manual re-keying.
Factur-X was developed jointly by France's FNFE-MPE and Germany's FeRD (the same organization behind ZUGFeRD) as a shared Franco-German standard. Since ZUGFeRD 2.0, released in 2019, the two formats have used the same underlying UN/CEFACT Cross Industry Invoice (CII) XML syntax and the same EN 16931 European e-invoicing semantic standard. The practical result: a properly built ZUGFeRD 2.x PDF and a Factur-X PDF are interchangeable. The current joint release is published as Factur-X 1.09.2 / ZUGFeRD 2.5.2 — one specification with two names, depending on which side of the Rhine you're standing on.
## Why Factur-X, Specifically, for France
France's e-invoicing and e-reporting reform, administered by the Direction Générale des Finances Publiques (DGFiP), requires domestic B2B invoices to move through state-registered *plateformes agréées* (approved platforms, formerly called PDPs) rather than as unstructured PDFs or paper. The reform recognizes three structured formats: UBL 2.1, CII, and Factur-X. Of the three, Factur-X is the one most small and mid-sized businesses gravitate toward, because the visible PDF layer means a human can still open and read the invoice directly — no dedicated viewer or translation step required — while the embedded XML satisfies the platform and reporting requirements.
The rollout is phased by company size:
- **September 1, 2026:** Every VAT-registered business in France must be able to *receive* compliant e-invoices. Large enterprises and ETIs (intermediate-sized companies) must also be able to *issue* them.
- **September 1, 2027:** SMEs and micro-enterprises join the issuing obligation, along with certain non-established taxable persons operating in France.
France's National Assembly rejected a proposed further delay to this timeline in 2025, and the DGFiP's subsequent readiness guidance has reinforced that these dates are holding. If your invoicing pipeline touches French customers or suppliers, the safest assumption is that these deadlines arrive on schedule.
## Factur-X Has Profiles — Choose the Right One
Not every Factur-X invoice carries the same amount of structured data. The specification defines five profiles, each a superset of the one before it:
- **MINIMUM** — bare invoice identification only: number, date, parties, currency, and document-level totals. No line items.
- **BASIC WL** (Without Lines) — adds more header-level detail but still no line items. This is the minimum profile accepted under the French reform for simple invoices.
- **BASIC** — the first profile to include line-item detail.
- **EN 16931** (also called Comfort) — full alignment with the European EN 16931 semantic standard. This is the profile most businesses should target, since it guarantees interoperability with other EN 16931-compliant formats and platforms.
- **EXTENDED** — everything in EN 16931 plus additional fields for sector-specific or national requirements. France defines its own EXTENDED-CTC-FR variant for flows that need it.
A file simply being "a Factur-X PDF" doesn't by itself guarantee EN 16931 compliance — that depends on which profile you generate and whether every required field for that profile is actually populated. For most businesses preparing for the French mandate, EN 16931 is the profile to build toward.
## How to Build a Factur-X-Compliant PDF
Structurally, creating a Factur-X invoice comes down to the same four steps whether you call it Factur-X or ZUGFeRD:
**1. Convert the PDF to PDF/A-3.** Factur-X requires the PDF/A-3 archival format specifically, because it's the only PDF/A variant that allows embedding files — like your invoice XML — that aren't themselves required to be PDF/A-compliant.
**2. Prepare a compliant invoice XML.** The XML mu...
### Automate PDF Generation from Data and Markdown
**URL:** https://www.datalogics.com/automate-pdf-generation-from-data-and-markdown
Manual invoice formatting and fragile Markdown-to-PDF pipelines don't scale. See how two real samples generate accessible, secure PDFs directly from structured data and plain text, with no browser or third-party renderer required.
Every business generates recurring documents: invoices, statements, reports, contracts, release notes, and knowledge base articles. Yet many organizations still rely on templates, manual formatting, or multi-step conversion pipelines to produce PDFs.
As document volume grows, those workflows become expensive to maintain, prone to errors, and difficult to standardize. Accessibility requirements, document security, and brand consistency only add more complexity.
If your content already exists as structured data or plain text, why shouldn't you be able to generate polished, accessible PDFs directly?
The answer is yes, and the following examples demonstrate two common approaches.
## Generate Professional Documents from Structured Data
Many business documents follow the same pattern: structured data combined with a reusable layout. Invoices, purchase orders, statements, contracts, and shipping manifests all fit this model.
Traditional workflows often rely on spreadsheets, Word templates, or manual editing to assemble these documents. As requirements change, templates drift out of sync, formatting breaks, and multiple versions begin circulating across teams.
A better approach is to generate documents programmatically.
Our invoice sample accepts structured business data, including customer information, line items, taxes, and payment terms, and produces a complete, professionally formatted PDF. Logos, tables, totals, and branding are applied automatically, ensuring every invoice is generated consistently without manual intervention.
For developers, this eliminates much of the custom code typically required to merge templates, manage layouts, and validate output. Instead of maintaining separate tools for document creation, accessibility, and security, a single API handles the entire workflow, making it well suited for scheduled jobs, web applications, document services, and other automated processes.
The benefits extend beyond automation.
- **Accessibility is built in.** The generated PDF includes semantic structure such as headings, tables, and figure labels, allowing screen readers and other assistive technologies to interpret the document correctly. Tagged PDFs are increasingly required for customer-facing documents and regulatory compliance.
- **Security is applied during generation.** Document permissions and encryption can be added as part of the same workflow, allowing recipients to view or print the document while preventing unauthorized editing.
The result is a document generation process that produces consistent, accessible, and secure PDFs at any scale.
## Convert Markdown Directly to PDF
Not every document begins as structured business data. Documentation, release notes, technical manuals, reports, and knowledge base articles are often written in Markdown.
Many Markdown-to-PDF workflows rely on HTML conversion, browser rendering, and PDF printing. While effective, those pipelines introduce additional dependencies and increase the likelihood of inconsistent output across environments. Browser updates, font differences, and rendering changes can all affect the final document.
Our Markdown sample demonstrates a more direct approach.
Markdown is converted directly into a fully formatted, tagged PDF without generating HTML, launching a browser, or relying on an external rendering engine. Tables, lists, code blocks, hyperlinks, images, and multilingual text are all supported while maintaining predictable output across platforms.
For development teams, this simplifies deployment by reducing external dependencies and eliminating an entire rendering pipeline.
The advantages include:
- **Fewer components to maintain.** One SDK replaces multiple tools and rendering libraries.
- **Predictable output.** Documents render consistently without relying on browser behavior or HTML print engines.
- **Accessible PDFs by default.** The generated document includes the semantic structure needed for screen readers and other assistive technologies.
## One Capability, Two Starting Points
Although these examples begin with different inputs, they solve the same problem.
Whether your content starts as structured business data or authored Markdown, it can be transformed directly into a professional PDF through a single, programmatic workflow. There is no need for manual formatting, template editing, browser automation, or complex document-generation pipelines.
For organizations generating invoices, reports, documentation, contracts, or other recurring business documents, this means less code to maintain, fewer moving parts to support, and more predictable output. Accessibility and document security become part of the generation process rather than additional steps performed afterward.
Automated PDF generation is no longer just about creating documents faster. It's about building document workflows that are reliable, maintainable, and ready for production from the start.
Both examples are available as comple...
### Getting Started with Adobe PDF Library 21 Using AI Coding Agents
**URL:** https://www.datalogics.com/getting-started-apdfl-21-ai-coding-agents
Adobe PDF Library (APDFL) 21 is Datalogics's most capable PDF SDK, built on the same Adobe source code that powers Acrobat. Whether you're working in Modern C++, Adobe C/C++, .NET, .NET Framework, or Java, you can now accelerate your integration using AI coding agents — Claude Code, Codex, Cursor, and others — connected to Datalogics's Scout MCP server.
This guide walks through getting a trial license, connecting your AI agent to Scout, installing APDFL 21 for your language of choice, and putting your agent to work generating and debugging code against the SDK.
::tldr
- Connect any MCP-compatible AI client to Datalogics's Scout server to query APDFL APIs, methods, and implementation patterns without leaving your editor.
- Grab a free trial activation key before writing any code — you'll need it for every language interface.
- APDFL 21 supports .NET, .NET Framework, Java, Modern C++, and the classic Adobe C/C++ interface, each with its own install path.
- Modern C++ is a new C++17 interface with RAII resource management and exception-driven error handling; the classic Adobe C/C++ interface remains fully supported.
- Once Scout is connected, your AI agent can generate starter code, explain API Reference methods, and help debug integration issues.
::
## What Is the Scout MCP Server?
Datalogics exposes Scout, an AI assistant with deep knowledge of the Adobe PDF Library SDK and its documentation, as an MCP (Model Context Protocol) server. Developers using MCP-compatible clients like Claude Desktop, Claude Code, Codex, or Cursor can connect directly to Scout and query the SDK's APIs, methods, and implementation patterns — without leaving their editor.
**MCP endpoint:** `https://datalogics.mcp.kapa.ai`
Add this endpoint in your AI client's MCP server settings and authenticate as required by your client.
Once connected, you can ask Scout questions like:
- "How do I merge two PDFs in APDFL .NET?"
- "Show me how to add a digital signature in Java."
- "What's the Modern C++ way to extract text from a PDF?"
::callout{type="info" title="Client-Specific Setup"}
For the specific steps to add `https://datalogics.mcp.kapa.ai` to Claude Code, Codex, or Cursor's MCP settings, refer to each client's own documentation for adding a remote MCP server endpoint, then authenticate using your Datalogics credentials.
::
## Step 1: Get Your Free Trial License Key
Before writing any code, obtain a free trial activation key:
1. Visit the [Adobe PDF Library free trial page](/adobe-pdf-library).
2. Fill out the form and submit.
3. Save your activation key — you'll need it for every language interface.
## Step 2: Connect Your AI Agent to Scout
In your MCP-compatible client (Claude Code, Codex, Cursor, etc.), add the Datalogics MCP server endpoint:
```
https://datalogics.mcp.kapa.ai
```
Once connected, your AI agent can answer implementation questions, generate boilerplate, and guide you through the SDK — for any of the language interfaces below.
## Step 3: Install APDFL 21 for Your Language
### .NET (C# / VB.NET)
Install via NuGet:
1. In Visual Studio 2022 or VS Code, go to **Tools → NuGet Package Manager → Manage NuGet Packages for Solution.**
2. Search for **Datalogics** and select **Adobe.PDF.Library.LM.NET**.
3. Install and accept the license terms.
Activate your license in code:
```csharp
Library.LicenseKey = "xxxx-xxxx-xxxx-xxxx";
using (Library lib = new Library())
{
// Your APDFL code here
}
```
Or run a sample via the `dotnet` CLI:
```bash
cd ./Images/RasterizePage
dotnet build
dotnet run
```
**Resources:**
- [Getting Started (.NET)](https://dev.datalogics.com/adobe-pdf-library-21/dot-net/getting-started)
- [API Reference](https://docs.datalogics.com/apdfl21/DotNet/)
- [C# .NET Samples on GitHub](https://github.com/datalogics/apdfl-csharp-dotnet-samples)
- [VB.NET Samples on GitHub](https://github.com/datalogics/apdfl-vb-dotnet-samples)
### .NET Framework (C# / VB.NET)
The setup mirrors .NET above — install **Adobe.PDF.Library.LM.NET** via NuGet in Visual Studio 2022.
**Resources:**
- [Getting Started (.NET Framework)](https://dev.datalogics.com/adobe-pdf-library-21/dot-net-fw/getting-started)
- [API Reference](https://docs.datalogics.com/apdfl21/DotNetFramework/)
- [.NET Framework Samples on GitHub](https://github.com/datalogics/apdfl-csharp-dotnet-framework-samples)
- [VB.NET Samples on GitHub](https://github.com/datalogics/apdfl-vb-dotnet-samples)
### Java (Maven)
Install via Maven:
1. Go to Datalogics Adobe PDF Library on Maven Central.
2. Copy the dependency snippet and paste it into the `dependencies` section of your `pom.xml`:
```xml [pom.xml]
com.datalogics.pdfl
pdfl
```
3. Provide your activation key when prompted on first run.
**Resources:**
- [Getting Started (Java)](https://dev.datalogics.com/adobe-pdf-library-21/java/getting-started)
- [API Reference](ht...
### Adobe PDF Library 21 Expands with .NET and Java Support
**URL:** https://www.datalogics.com/blog-adobe-pdf-library-21-expands
We've updated Adobe PDF Library 21 with a set of improvements focused on broader language support, updated package distributions, and refinements across the SDK. Here's what's new.
Adobe PDF Library 21 has grown beyond its C/C++ roots, and this release pushes that expansion further. If your team builds in .NET or Java, or if you're managing document workflows that need broader OCR and font coverage, this update changes what's available to you without touching your existing integration.
Datalogics has updated Adobe PDF Library 21 with expanded language support, refreshed package distributions, and a handful of refinements across the SDK. Here's what's new, and what it means for teams evaluating or already running APDFL.
::tldr
- Adobe PDF Library 21 now fully supports .NET, .NET Framework, and Java, alongside Adobe C/C++ and Modern C++.
- NuGet and Maven packages are both updated to version 21.0.0 for easier dependency management.
- OCR now recognizes Vietnamese text, adding to the library's global document coverage.
- Forms Extension installers support the Modern C++ interface, and XPS2PDF now surfaces clearer errors for missing joboptions files.
- Existing Adobe C/C++ integrations are unaffected — no changes required to adopt this release.
::
## Expanded Programming Language Support
Adobe PDF Library 21 now supports **.NET**, **.NET Framework**, and **Java**, joining Adobe C/C++ and Modern C++ as fully supported development options.
This means teams building in .NET or Java environments can integrate Adobe PDF Library directly into their existing stack, without standing up a separate C++ development environment. Combined with the Modern C++ SDK introduced earlier in the v21 line, developers across a much wider range of technology stacks now have a direct path to building PDF functionality into their applications.
::callout{type="success" title="No Migration Required"}
If you're already on Adobe C/C++, nothing changes for you. The new language support is additive, not a replacement path.
::
## Updated Packages: NuGet and Maven
To support this expanded language coverage, both major package distributions have been updated:
| Package | Version |
|---|---|
| NuGet | 21.0.0 |
| Maven | 21.0.0 |
.NET and Java developers can now pull the latest Adobe PDF Library release directly through the package managers they already use.
```bash
dotnet add package Datalogics.PDFL --version 21.0.0
```
```xml [pom.xml]
com.datalogics
pdfl
21.0.0
```
## Expanded OCR Language Support: Vietnamese
OCR language support has been expanded to include **Vietnamese** text recognition, giving developers broader coverage for recognizing and digitizing documents in additional global markets.
## Additional Changes in This Release
- Forms Extension installers now support the :badge[NEW]{type="new"} Modern C++ interface.
- The XPS2PDF plugin now reports a specific error when the joboptions file cannot be found, making troubleshooting easier.
::callout{type="warning" title="Missing Joboptions File"}
If XPS2PDF previously failed silently or with a generic error on a missing joboptions file, expect a clearer, more specific error message going forward.
::
## A Quick Recap: Also in Adobe PDF Library 21
These updates build on the broader v21 release, which introduced:
- A **Modern C++ SDK** built to C++17 standards, with RAII-based resource management, exception-based error handling, and a unified `datalogics_interface` namespace.
- A new **WebToPDF** plugin for converting HTML (via URL or file tree) directly to PDF.
- **GB18030** font support for accurate Simplified and Traditional Chinese rendering.
- A new `ListStructureTree` sample for inspecting tagged PDF structure, useful for accessibility and PDF/UA workflows.
::callout{type="info" title="No Breaking Changes"}
Existing Adobe C/C++ integrations remain fully supported, and none of these updates require any changes to current implementations.
::
## Next Steps
Whether you're working in Adobe C/C++, Modern C++, .NET, or Java, this release gives you a path to broader language support, simpler package management, and expanded OCR coverage.
- [Download the latest release](https://www.datalogics.com/adobe-pdf-library) of Adobe PDF Library 21.
- Explore the Modern C++ SDK if you're starting a new integration.
- [Contact Datalogics](/datalogics-contact-us) to discuss migrating or extending your PDF pipeline.
### Adobe PDF Library vs. Apryse vs. Nutrient: Which PDF SDK Should You Choose?
**URL:** https://www.datalogics.com/adobe-pdf-library-vs-apryse-vs-nutrient
A vendor-neutral comparison of three leading PDF SDKs — Adobe PDF Library, Apryse, and Nutrient — covering rendering fidelity, platform coverage, security certifications, standards compliance, and licensing to help developers choose the right one.
If you're building an application that needs to create, edit, render, or extract data from PDFs, you have a decision to make early on: build it yourself on top of an open-source library, or license a commercial PDF SDK. For most teams working at any real scale — enterprise document workflows, high-volume processing, or anything that needs to look pixel-perfect — a commercial SDK saves months of engineering time.
Three of the most established names in this space are Adobe PDF Library (from Datalogics), Apryse, and Nutrient (formerly PSPDFKit). All three let developers embed PDF functionality directly into their own applications rather than relying on end-user software like Acrobat. One structural difference sets them apart from the start: Adobe PDF Library shares its core source code with Adobe Acrobat, while Apryse and Nutrient have each built or acquired their rendering engines independently. Whether that matters for your project depends on what you're optimizing for — which is really what the rest of this comparison is about.
Beyond that, the three products take meaningfully different approaches, and the right choice depends heavily on your platform, your use case, and how much of the document lifecycle you need to own. Read our feature comparison below and the more detailed analysis after the chart.
## Feature comparison at a glance
| Capability | Adobe PDF Library (Datalogics) | Apryse | Nutrient |
|---|---|---|---|
| **Processing SDK** | ✓ | ✓ | ✓ |
| **Ready-made UI (viewer/editor components)** | No — designed to embed in your application | Yes — WebViewer, mobile UI components | Yes — Web SDK, Document Authoring UI |
| **REST / cloud API** | Via pdfRest API Toolkit | Yes | Yes — DWS Viewer & Processor APIs |
| **Container deployment** | ✓ (pdfRest API Toolkit Container) | ✓ | ✓ (Document Engine) |
| **Docker support** | ✓ | ✓ | ✓ |
| **Kubernetes support** | ✓ | ✓ | ✓ |
| **Rendering engine** | Adobe's own engine — same codebase as Acrobat | Built in-house or via acquisitions| Built on PDFium (the open-source engine used in Chrome and Android) |
| **PDF spec fidelity** | Native, first-party (Acrobat) | Proprietary reimplementation | Built on PDFium, with proprietary tooling layered on top |
| **Core languages** | C/C++ (Adobe & Modern C++), .NET/.NET Framework (VB.NET), Java (Kotlin) | C++, Java, .NET/.NET Core, JavaScript/TypeScript, Node.js, Python, Go, Ruby, PHP, Swift | .NET, Java, Python, Node.js, JavaScript |
| **Mobile support** | Not a primary focus | iOS, Android | iOS, Android, React Native, Flutter, .NET MAUI, Xamarin, visionOS |
| **OCR language coverage** | 100+ languages (any language supported by Tesseract) | 80+ languages (default module); IRIS add-on for complex layouts | 30+ languages |
| **PDF/A support** | PDF/A-1 through PDF/A-4 | PDF/A-1 through PDF/A-4 | PDF/A supported for archiving; specific conformance-level coverage isn't fully documented publicly |
| **PDF/X support** | PDF/X-1a, X-3, X-4, X-5, X-6| PDF/X-1a, X-3, X-4, X-5, X-6 | Not clearly documented publicly |
| **ZUGFeRD / Factur-X e-invoicing** | ✓ | ✓ | Not clearly documented publicly |
| **XFA forms** | Import/export, flatten static and dynamic XFA, convert XFA to AcroForm | Limited — static XFA and AcroForms fully supported; dynamic XFA needs an add-on/workaround | Not supported — convert to AcroForms or flatten first |
| **Digital signatures** | PAdES, CMS, RFC 3161 timestamping, PAdES policy signatures | PAdES-style and certificate-authority-backed signatures | PAdES and CAdES, client-side/server-side/client-server signing architectures |
| **Redaction** | "True redaction" — removes content while keeping documents searchable | "True redaction" — removes content while keeping documents searchable | ✓, with audit-ready tracking |
| **Real-time / collaborative editing** | Not a focus (server-side, batch-oriented model) | Annotation collaboration supported | Strong focus — Instant Collaboration, live multi-user editing, cursor/presence tracking |
| **Security certifications** | SOC 2 Type 2, audit report available on request | SOC 2 Type 2, ISO/IEC 27001:2022 | SOC 2 Type 2-audited infrastructure (per Nutrient) |
| **Enterprise support** | ✓ | ✓ | ✓ |
| **Licensing model** | Annual license (OEM, SaaS, or end-user tiers); end-user licenses start around **$5,999** and fixed fee unlimited distribution options available| Contact sales / custom quote | Contact sales / custom quote |
*A blank or "not clearly documented" cell doesn't necessarily mean a feature is unavailable — it means it wasn't a clearly published, specific claim on that vendor's public materials at the time of writing. Always confirm specifics (especially PDF/X and ZUGFeRD coverage for Nutrient, and exact XFA behavior for Apryse) directly against current vendor documentation before making a purchasing decision.*
## Who each product is for
**Adobe PDF Library**, licensed exclusively through Datalogics, brings Acrobat-level rendering fidelity and...
### Converting PDFs to Word, Excel, and PowerPoint with Adobe PDF Library: A Complete Developer Guide
**URL:** https://www.datalogics.com/converting-pd-fs-to-word-excel-and-power-point-with-adobe-pdf-library-a-complete-developer-guide
Legal teams need to redline a contract that only exists as a PDF. Finance teams need last quarter's numbers out of a PDF statement and into a spreadsheet they can actually pivot. Content teams need to turn an archived PDF report into a template they can reuse. In every one of these cases, the PDF isn't the problem — the fact that it's *read-only* is. Converting that PDF into a native Microsoft Office format is usually the fastest way to unblock the downstream work.
Adobe PDF Library (APDFL) handles this conversion directly in your application code through a `ConvertToOffice` function that outputs Word (`.docx`), Excel (`.xlsx`), and PowerPoint (`.pptx`) files. This guide walks through the whole process end to end: setting up the project, running a basic conversion, deciding which output format fits your input, handling scanned PDFs (which need OCR before conversion will produce anything usable), and wiring all of it into a batch pipeline. Examples use APDFL 21 and .NET.
::tldr
- Use `Document.ConvertToWord`, `ConvertToExcel`, and `ConvertToPowerPoint` to convert PDFs to editable Office formats directly from C# code.
- Pick your output format based on content shape: Word for text-heavy documents, Excel for tabular data, PowerPoint for slide-style layouts.
- Conversion fidelity depends entirely on how the source PDF was produced — born-digital PDFs convert cleanly, scanned PDFs need an OCR pass first or they'll convert into empty or image-only files.
- Always check the boolean return value; a `false` result usually means the source PDF is encrypted, malformed, or too complex to parse.
- The conversion API is Windows and Linux only today, which matters for pipeline and container planning.
::
## Why Convert PDFs Back to Editable Formats
Most enterprise PDF archives exist because PDF is excellent at preserving a finished, final-form document. That's also exactly why it's a poor starting point for the next round of edits. Converting a PDF back into an Office format restores editability, lets you adjust layout and formatting, and makes the content usable in tools your collaborators already know. It can also make the content more accessible to people using assistive technology built for Office formats.
APDFL bakes this conversion into the same SDK you're already using for PDF creation, manipulation, and compliance work, so you don't need a separate conversion service or a manual "export as" step in someone's desktop workflow.
## Setting Up Your .NET Project
Install the NuGet package and restore before writing any conversion code.
```powershell
dotnet add package Adobe.PDF.Library.LM.NET
dotnet restore
```
Every APDFL program needs to activate a license and initialize the library before calling any conversion function. Adapted from the license pattern documented in the [.NET samples README (develop-21)](https://github.com/datalogics/apdfl-csharp-dotnet-samples/tree/develop-21):
```csharp [Program.cs]
using Datalogics.PDFL;
Library.LicenseKey = "xxxx-xxxx-xxxx-xxxx";
using (Library lib = new Library())
{
// ConvertToOffice calls go here
}
```
::callout{type="warning" title="Activate Before You Instantiate"}
Set `Library.LicenseKey` **before** creating the `Library` instance, not after. If you skip activation entirely, the sample will prompt for a trial key on the console the first time you run it.
::
## How ConvertToOffice Works Under the Hood
`ConvertToOffice` doesn't just embed a PDF inside an Office wrapper — it does real structural analysis. Understanding this up front explains why some PDFs convert beautifully and others don't, which matters for the format choice and OCR steps below.
The library analyzes the PDF's content streams, identifies text blocks, tables, and graphic elements, and maps them to the appropriate Office constructs. Text formatting, column structure, and embedded images are preserved where the target format supports them. The quality of that mapping depends entirely on how the source PDF was created: PDFs generated from Office documents convert with high fidelity, while scanned PDFs or PDFs from non-standard sources may need OCR pre-processing or produce less structured output.
## Converting a PDF to Word, Excel, and PowerPoint in C#
The .NET interface exposes conversion as three static methods on the `Document` class: [`ConvertToWord`](https://docs.datalogics.com/apdfl21/DotNet/APDFL21.0.0PlusP1c/class/Document#ConvertToWord), [`ConvertToExcel`](https://docs.datalogics.com/apdfl21/DotNet/APDFL21.0.0PlusP1c/class/Document#ConvertToExcel), and [`ConvertToPowerPoint`](https://docs.datalogics.com/apdfl21/DotNet/APDFL21.0.0PlusP1c/class/Document#ConvertToPowerPoint), each taking an input PDF path and an output Office file path and returning a boolean success flag. The function takes three arguments under the hood: the input path, the output path, and the default file system reference. An `ASBool` return value indicates success or failure — each conversion function is independ...
### How PDF Form Flattening Breaks Document Workflows
**URL:** https://www.datalogics.com/how-pdf-form-flattening-breaks-document-workflows
Explaining four timing mistakes that cause PDF form flattening to silently break document pipelines, including blank outputs, failed archives, invalidated signatures, and stripped field data.
Every PDF workflow reaches a
point of no return, the moment an editable form becomes a permanent record.
Flattening is that moment. It converts interactive fields into static page
content, strips the editable structure, and hands downstream systems a document
that can no longer be changed.
Get the timing right and your
pipeline produces clean, compatible, tamper-resistant records. Get it wrong and
you get blank outputs, failed archives, broken signatures, or silent data loss
that only surfaces weeks after the fact.
The four mistakes below account
for the majority of flattening failures in production document pipelines. What
they have in common: each one treats flattening as a mechanical final step
rather than a deliberate architectural decision.
Mistake 1: Flattening Before Data Import
A PDF template is generated,
flattening runs automatically, and then the workflow attempts to populate
fields from an XML, XFDF, FDF, or database source. The fields don’t exist
anymore. The import either fails silently or produces a blank document.
This is the most common failure
mode in automated document generation, and it’s particularly insidious because
it often doesn’t throw an error — it just produces empty output. A pipeline
that ran fine in development can suddenly generate blank forms in production
after an operations change shuffles the step order.
The symptom that shows up in
support tickets: “The PDFs are coming out blank.” The actual cause: flattening
happened two steps before it should have.
The fix: Data in,
validated, then flattened.
Import Data → Validate Fields
→ Flatten PDF → Archive or Distribute
Mistake 2: Flattening Before Signatures Are Applied
The form is flattened to “lock
it down” before it goes out for signing. The signature fields are now gone.
Recipients either can’t sign or the signing platform rejects the document
entirely.
Organizations that apply a
blanket flatten-on-ingest policy are especially prone to this. The policy makes
sense for truly finalized documents, but approval workflows, contracts, and
multi-reviewer packets aren’t finalized — they’re still in transit.
The situation is worse with
cryptographic digital signatures. These rely on the document structure
remaining unchanged between the moment of signing and the moment of validation.
Flatten in the wrong place and the signature becomes unverifiable, or the entire
workflow has to restart from scratch.
Flattening locks the document.
Signing needs to happen before the lock.
The fix: All reviews,
approvals, and signatures complete first.
Generate Form → Review &
Approve → Apply All Signatures → Flatten → Archive
If you have ever been told to
"flatten" a PDF form before sending it, archiving it, or running it
through a document pipeline, you may have wondered what that actually means. It
sounds like a technical operation, but the concept is straightforward once you
understand what a PDF form is made of.
This guide explains PDF form
flattening in plain language, walks through what happens to your data, and
covers the three most common scenarios where flattening is the right move.
What Is an Interactive PDF Form?
A standard PDF form is not a
static document. It contains interactive elements: text fields where users
type, checkboxes they can check or uncheck, dropdown menus, radio buttons, and
signature fields. These elements are separate from the underlying page content.
They float above the page as a layer of interactive components called
annotations and form fields.
This layered structure is what
makes PDF forms useful for data collection. But it also makes them fragile. Not
every PDF viewer can render every form type correctly. Not every printing
system knows what to do with interactive fields. And not every archiving
platform accepts PDFs that still contain live, editable data.
What Happens When You Flatten a PDF Form?
Flattening merges the
interactive layer into the static page content. The form fields disappear. In
their place, the data that was entered into those fields becomes permanent
text, images, or drawings baked directly into the page.
After flattening:
The data is still visible. If a
user typed "John Smith" into the Name field, "John Smith"
now appears as permanent text on the page.
The fields are gone. There are
no text boxes to click, no checkboxes to toggle, no dropdowns to open. The
document looks the same visually, but it is no longer interactive.
The file cannot be edited.
Because the form fields no longer exist, there is nothing to fill in or change.
The document is locked.
The file is smaller. Interactive
form fields add overhead to a PDF file. Removing them typically reduces file
size.
Checkboxes become drawings. A
checked checkbox becomes a static checkmark image. An unchecked checkbox
becomes an empty box. Either way, it is now a permanent part of the page.
Barcodes are preserved. If the
form contained barcode fields, the barcode pattern is retained as a static
image in the output.
What Happens to the Data?
This is the most common
question, and the answer is: the data is preserved. Flattening does not delete
what was entered into the form. It converts that data from an editable field
value into permanent page content.
PDF form flattening is often
treated as a technical operation, something developers handle in a pipeline.
But the reason organizations flatten forms is almost always a compliance
requirement: they need a final, tamper-proof record that can be stored, submitted,
or audited.
The five scenarios below are the
most common places where form flattening intersects with real regulatory and
operational requirements. Each one represents a situation where failing to
flatten, or failing to flatten correctly at scale, creates risk.
Scenario 1: Healthcare: Patient Form
Archiving for HIPAA and PDF/A
Healthcare organizations collect
completed forms from patients at every stage of care: intake forms, consent
forms, clinical questionnaires, authorization documents. These forms are
collected as interactive PDFs, completed electronically, and then need to be
entered into electronic health record (EHR) systems or document management
platforms as part of the permanent patient record.
The problem is that interactive
PDF forms are not acceptable inputs for most EHR archiving systems. Dynamic XFA
forms are specifically prohibited under the PDF/A standard, which is the format
required by many long-term retention policies. Forms with live field
annotations fail PDF/A validation and cannot be entered into compliant
archives.
Flattening solves this at the
point of submission. After a patient completes and submits a form, the PDF is
flattened automatically before it enters the archiving workflow. The result is
a static, PDF/A-compatible document containing the patient's responses as
permanent page content with no live fields, no XFA dependencies, no archival
validation failures.
For organizations processing
hundreds of forms per day, this is a batch operation that runs continuously as
part of the intake pipeline. PDF Forms Flattener handles this from the command
line on Windows or Linux servers without requiring an Acrobat installation on
every processing machine.
Talk to a Datalogics developer
about automating your healthcare forms workflow: datalogics.com/contact.
Scenario 2: Financial Services: Regulatory
Submissions and Audit Trails
Financial institutions collect
forms throughout the customer lifecycle: account opening documents, KYC (Know
Your Customer) forms, loan applications, investment suitability questionnaires.
Regulators -- the SEC, FINRA, OCC, and state-level authorities -- require that
these records be maintained as tamper-proof, final documents that cannot be
altered after submission.
An interactive PDF form is not a
tamper-proof record. Field values can be changed after submission. A form with
live AcroForm or XFA fields does not provide the assurance of finality that a
regulatory audit requires.
Flattening converts the
submitted form into a non-editable static document that accurately reflects the
state of the record at the time of submission. This is the financial services
equivalent of a wet signature on paper: the document is locked, the record is
permanent, and any future audit can review a document that cannot have been
altered after the fact.
High-volume environments like...
### Getting Started with PDF Forms Flattener: Flatten Your First PDF in Under 10 Minutes
**URL:** https://www.datalogics.com/getting-started-with-pdf-forms-flattener-flatten-tutorial
You have your activation key. Here is how to install PDF Forms Flattener, run your first flatten command, import data before flattening, and convert XFA to AcroForm in under 10 minutes.
You have your activation key (if
not, “Before You Start” has you covered!). Here is how to go from installation
to a successfully flattened PDF in under 10 minutes.
This guide covers the four
operations you will use most: basic installation and verification, flattening a
single PDF, importing data before flattening, and converting XFA form fields to
AcroForm. For the full parameter reference, the documentation is at
docs.datalogics.com.
Before You Start
You will need: your PDF Forms
Flattener activation key, the installer file for your operating system (.exe
for Windows, .bsx for Linux), and at least one PDF with form fields to test
with.
If you do not have a trial key
yet, request one at datalogics.com/flatten-pdf-forms. No credit card required.
Step 1: Install and Verify
Windows
Run the .exe installer. Accept
the license agreement, choose your installation directory, and paste your
activation key when prompted. The installer adds PDFFormsFlattener to your
system path.
Open a Command Prompt or
PowerShell window and run:
PDFFormsFlattener --help
You should see the help output
listing available parameters. If you see a "command not found" error,
verify that the installation directory is in your system PATH.
Linux
Navigate to the directory
containing the .bsx installer and make it executable:
chmod +x PDFFormsFlattener.bsx
./PDFFormsFlattener.bsx
Follow the prompts and paste
your activation key when asked. After installation, verify from your terminal:
PDFFormsFlattener --help
If the command is not found,
check whether the install directory is in your PATH and add it if needed.
Step 2: Flatten Your First PDF
Run the basic flatten command:
PDFFormsFlattener --input
    form.pdf --output flattened.pdf --flatten true
PDF forms fail in automated
pipelines in predictable ways. The same five problems show up repeatedly across
document intake systems, generation pipelines, archiving workflows, and
distribution systems. Each one has a root cause and a fix.
This guide covers the five most
common failure modes, explains what is actually happening technically, and
shows how to resolve each one. Most solutions involve flattening or converting
the form at the right point in the pipeline -- something PDF Forms Flattener
handles from the command line without requiring changes to your application
code.
Problem 1: The Processed PDF Comes Out Blank
A dynamic XFA form enters your
pipeline. Your processing tool opens it, runs its operation, and produces
output. The output PDF is blank -- no content, no form fields, nothing.
Root cause: your processing tool
does not include an XFA rendering engine. Dynamic XFA forms have no PDF-based
page content. The entire layout is generated at open time by an XFA renderer.
If the tool that opens the file does not have a full XFA rendering engine, it
cannot produce any visible output. It sees an empty PDF structure with embedded
XML data and has nothing to render.
Fix: flatten the XFA form before
it enters your processing pipeline. PDF Forms Flattener converts dynamic XFA to
a static PDF with all content rendered as permanent page elements. The
flattened output can be opened and processed correctly by any tool, regardless
of XFA support.
PDFFormsFlattener --input xfa-form.pdf
        --output flattened.pdf --flatten true
Feed the flattened output into
your downstream processing tool instead of the original XFA.
Problem 2: Your Archiving System Rejects the
Forms
Forms that pass through your
intake workflow fail when submitted to your document management or archiving
system. The error is a PDF/A validation failure.
Root cause: the form contains
XFA markup, which is explicitly prohibited in PDF/A (ISO 19005, all versions).
Any PDF containing XFA fails PDF/A conformance validation regardless of whether
the rest of the document meets the standard. Some archiving systems also reject
PDFs with live interactive annotations even when XFA is not present.
Fix: flatten the forms before
they reach your archiving system. The flattened output has no XFA markup and no
interactive annotations, just static PDF content that passes PDF/A
validation.
For a one-time remediation of an
existing backlog:
PDFFormsFlattener --input
        /forms-archive/ --output /flattened-archive/ --flatten true
For ongoing intake, add the
flatten step to your pipeline before the archiving submission step. Every form
that enters the archive arrives already flattened and validated.
If you are a developer or IT
admin who needs to flatten PDF forms in batch -- AcroForms, static XFA, or
dynamic XFA -- this guide walks through the full workflow using PDF Forms
Flattener from the command line.
By the end, you will have run
your first flatten, processed a directory of PDFs, imported data before
flattening, and seen how to convert XFA form fields to AcroForm. No Acrobat
required. No SDK integration needed.
What You Need Before You Start
A PDF Forms Flattener license or free trial key. The installer
for your operating system: .exe for Windows, .bsx for Linux. One or more PDF
files with form fields to test against.
PDF Forms Flattener runs on
Windows and Linux. There is no macOS version.
Step 1: Install PDF Forms Flattener
On Windows, run the .exe
installer and follow the prompts. When asked for your activation key, paste the
key you received from Datalogics.
On Linux, run the .bsx installer
from your terminal. Mark it executable first if needed:
chmod +x PDFFormsFlattener.bsx
./PDFFormsFlattener.bsx
Paste your activation key when
prompted.
After installation, verify the
tool is accessible by running it without arguments. You should see the help
output listing available parameters.
Step 2: Flatten a Single PDF
The basic flatten command takes
an input file, an output path, and the flatten flag:
PDFFormsFlattener --input
    input.pdf --output output.pdf --flatten true
This flattens all interactive
form fields in input.pdf and writes the result to output.pdf. The original file
is not modified.
What the output contains: all
data that was in the form fields is now permanent text or images on the page.
The form fields themselves are gone. The PDF is static and non-editable.
Try opening the output file in a
PDF viewer. The document should look identical to the original, but clicking on
a form field area will not activate an input box.
Step 3: Batch Process a Directory of PDFs
To process multiple files in one
pass, point the input flag at a directory...
### How PDF Form Flattening Fits Into Your Document Pipeline
**URL:** https://www.datalogics.com/how-pdf-form-flattening-fits-into-your-document-pipeline
A practical guide to where PDF form flattening belongs in your document workflow: intake, generation, archiving, and distribution -- and why getting the timing right matters.
PDF form flattening is not a one-size-fits-all operation you run at the end of a workflow. Where it belongs depends on what your pipeline is doing with the form: collecting data, generating documents from records, distributing finalized forms, or archiving completed submissions.
Getting the timing right matters. Flatten too early and you lock a form before data has been imported. Flatten too late and interactive fields create compatibility problems downstream. This guide walks through the four most common pipeline patterns and where flattening belongs in each one.
## Pattern 1: The Intake Pipeline
In an intake pipeline, users submit completed PDF forms -- employment applications, onboarding documents, service requests -- and those forms enter a processing system. The challenge is that incoming forms arrive as interactive PDFs with live AcroForm or XFA fields. Most document management systems, ECM platforms, and archiving systems want static PDF inputs, not interactive ones.
Flattening belongs at the point of receipt, immediately after submission and before any downstream routing. The incoming form is flattened as the first processing step. What enters the document management system is a static PDF with all field data preserved as permanent page content -- compatible with archival standards, printable by any system, and safe to route through automated review workflows.
For high-volume intake environments processing hundreds or thousands of submissions per day, this is a continuous batch operation. PDF Forms Flattener can be invoked as part of the intake script, processing each incoming file as it arrives or running against a directory of queued submissions on a schedule.
## Pattern 2: The Document Generation Pipeline
In a document generation pipeline, your system produces filled PDF forms from records -- populating templates with data pulled from a database, CRM, or other data source. The output is a finalized document: a pre-filled application, a generated contract, a populated disclosure form.
Here, flattening is the last step in the generation sequence. You populate the form template with data from your source system, then immediately flatten the populated result. The output is a locked static PDF that contains the generated data as permanent content. It cannot be altered by anyone who receives it, which is the correct behavior for a generated document delivered to a recipient.
PDF Forms Flattener supports this populate-then-flatten pattern with a single command. The `--import` parameter accepts FDF, XFDF, and XML data files for AcroForms, and XFD, XDP, and XML for XFA forms. One command imports the data and flattens the result: no intermediate step, no intermediate file that could be intercepted or altered between population and locking.
## Pattern 3: The Archive Pipeline
In an archive pipeline, the goal is long-term retention of completed forms in a format that guarantees future readability -- typically PDF/A, the ISO standard for archival documents. XFA forms are explicitly prohibited in PDF/A. AcroForms with live fields do not meet PDF/A requirements in many implementations.
Flattening is the remediation step that converts submitted forms into archival-ready documents. The flattened output is a static PDF that passes PDF/A validation, has no dependency on Adobe Acrobat or any XFA rendering engine, and will be readable by any compliant PDF viewer permanently.
For organizations with a backlog of historical XFA forms -- government agencies, healthcare systems, financial institutions -- this is typically a one-time batch migration followed by ongoing flattening as new submissions arrive. PDF Forms Flattener processes entire directories in a single command, making the batch migration a scripted operation rather than a manual task.
## Pattern 4: The Distribution Pipeline
In a distribution pipeline, finalized forms are sent to recipients: customers, regulators, auditors, or counterparties. The concern here is tamper-proofing. An interactive PDF sent to a recipient can have its field values changed -- whether accidentally, through a viewer that writes field state on open, or deliberately.
Flattening before distribution is the standard practice for anything with legal, financial, or compliance significance. The flattened PDF is what the recipient sees. Field values are permanent text on the page. There is nothing to click, nothing to modify, and the document accurately reflects what was submitted or generated at the time it was finalized.
This is particularly important for forms that pass through multiple hands before final disposition: a loan application reviewed by underwriting before going to compliance, a signed consent form copied to multiple parties, a generated disclosure sent to a customer and filed with a regulator simultaneously. Each recipient gets a static, non-editable record -- not a live form they could modify before forwarding.
## Choosing the Right Point to Flatten
The four ...
### Protect Your PDFs from AI Data Scraping
**URL:** https://www.datalogics.com/protect-your-pdfs-from-ai-data-scraping-tdm-rep-and-pdf-optimizer
AI models are training on publicly available PDFs, often without the knowledge or consent of content owners. PDF Optimizer now supports TDMRep, the W3C's machine-readable rights protocol, letting you embed AI data mining permissions automatically as part of your existing optimization workflow.
If your organization publishes
PDFs and you are concerned about AI models training on your content without
permission, you now have a way to signal that at the document level,
automatically, as part of your optimization workflow.
PDF Optimizer now supports
TDMRep, the W3C's Text and Data Mining Reservation Protocol. This means that
when you optimize a PDF for size, performance, or archival compliance, you can
simultaneously embed a machine-readable statement of your AI data rights into
the document's metadata. One processing pass. Both outcomes.
The Problem: AI Models Scrape PDFs
AI language and multimodal
models are trained on large corpora of text and document data scraped from the
web. PDFs are a significant source of that training data: research papers,
legal documents, financial reports, technical manuals, policy documents, and
published books are all regularly ingested by automated data collection
pipelines.
In many cases, this happens
without the knowledge of the content owner and without any mechanism for the
owner to signal whether they consent to that use. Standard access controls and
robots.txt directives were not designed with AI training data collection in
mind, and they are inconsistently observed by data collection systems.
For publishers, enterprises, and
institutions that publish PDFs publicly or semi-publicly, the risk is real:
proprietary research, confidential methodologies, or commercially valuable
content may be entering AI training pipelines without authorization.
What Is TDMRep?
TDMRep, which stands for Text
and Data Mining Reservation Protocol, is a standard developed by the W3C to
provide a machine-readable way for content owners to express their text and
data mining permissions. It operates at the metadata level, embedding the
rights statement directly in the document so that it travels with the PDF
wherever it goes.
The protocol consists of two
elements. The first is a boolean reservation flag: setting this to true signals
that text and data mining rights are reserved and that the content owner does
not grant permission for AI training use. The second is an optional policy URL,
pointing to a page where licensing information, contact details, or policy
terms can be found by parties who wish to request TDM access.
TDMRep is referenced in the EU's
implementation guidance for text and data mining provisions under the Copyright
Directive (DSM/CDSM), giving it legal standing in European jurisdictions. It is
supported by major European academic publishers and is gaining adoption among
rights-conscious content organizations globally.
What Is New: TDMRep in PDF Optimizer
PDF Optimizer now supports
adding TDMRep metadata to the XMP metadata block of any PDF processed through
the optimizer. When configured in your JSON profile, PDF Optimizer embeds the
tdm-reservation boolean and, optionally, a tdm-policy URL into the document's
XMP metadata during the optimization pass.
This means:
•
No additional tool or processing step is required. The
rights metadata is embedded as part of the same optimization workflow that
handles compression, color conversion, and PDF/A archiving.
Compliance archiving
requirements are rarely optional. Healthcare organizations must retain patient
records in formats that can be reproduced decades from now. Financial services
firms must archive client communications and transaction records to standards
that withstand regulatory examination. Government agencies must preserve public
records in formats that survive software platform changes. In all of these
cases, the standard most commonly required is PDF/A.
The challenge for most
organizations is not understanding what PDF/A requires. The challenge is
getting there at scale. If you have a repository of 500,000 existing PDFs that
need to be converted to compliance, or an ongoing pipeline producing thousands of
new PDFs per month that must be archived in compliant format, manual conversion
is not a realistic option.
This post covers what PDF/A
requires, how PDF Optimizer handles bulk conversion, and how to configure the
process for your specific compliance scenario.
What PDF/A Actually Requires
PDF/A (ISO 19005) is a
constrained version of the PDF specification designed for long-term
preservation. Its requirements exist to ensure that a document can be rendered
identically on any compliant viewer at any point in the future, without
depending on external resources, platform-specific features, or software that
may not exist in 20 years.
The core requirements are: all
fonts must be fully embedded in the document, color spaces must be explicitly
defined (no reliance on device color settings), encryption and password
protection are not permitted, JavaScript and executable content are prohibited,
and XFA (XML Forms Architecture) dynamic forms are not allowed. Interactive
elements that cannot be reliably reproduced without specific software must be
removed or flattened.
What this means in practice is
that many PDFs generated by standard enterprise software, whether document
management systems, report generators, or form processing tools, will not be
PDF/A compliant out of the box. They may reference external fonts, use device-dependent
color spaces, contain JavaScript for form interactions, or include metadata and
embedded objects that violate the standard. Producing compliant output requires
an explicit conversion step.
PDF/A-1b vs. PDF/A-3u: Choosing the Right Conformance Level
PDF/A comes in multiple
conformance levels, and choosing the right one for your workflow matters.
PDF/A-1b is the most widely
supported conformance level and the right starting point for most
organizations. It requires visual reproducibility: the document must look the
same on any compliant viewer. It does not require Unicode text mapping, which
means text in the document may not be machine-readable or searchable after
conversion. For workflows where the archived document is treated as a visual
record, PDF/A-1b is sufficient.
PDF/A-3u requires both visual
reproducibility and Unicode character mapping for all text in the document.
This means text in the archived document can be searched, extracted, and
processed by downstream systems. PDF/A-3u also allows any file type to be embedded
as an attachment within the PDF, making it suitable for workflows that need to
carry source data, XML exports, or supplementary files alongside the visual
document.
If your compliance requirement
involves downstream text extraction, full-text search across archived
documents, or the need to embed related files within the PDF, use PDF/A-3u. For
st...
### How to Build an Automated PDF Optimization Pipeline: Architecture Guide
**URL:** https://www.datalogics.com/how-to-build-an-automated-pdf-optimization-pipeline-architecture-guide
A technical architecture post for senior developers designing high-volume document processing infrastructure. Covers three pipeline patterns: simple batch, event-driven, and compliance. Includes command syntax and JSON profile configuration for each stage.
Suppose your system ingests
500,000 PDFs per month. Every one of them needs to be compressed to a
consistent target size, validated for structural integrity, and archived to
PDF/A compliance. Doing that manually is not possible. Doing it with a tool
that requires human input per document is not scalable. What you need is a
pipeline.
This post covers three PDF
optimization pipeline patterns: simple batch processing, event-driven
processing, and compliance-ready archival pipelines. For each, we walk through
the architecture, the relevant tools, and the command syntax that makes it work.
The Tools: PDF Checker and PDF Optimizer
Both pipelines described in this
post use two tools from Datalogics that are designed to work together. PDF
Checker is a diagnostic tool that validates PDF documents before they enter
your processing pipeline: it identifies structural errors, unembedded fonts,
invalid color spaces, and other issues that would cause downstream failures.
PDF Optimizer is the optimization engine that performs compression, color
conversion, PDF/A conversion, and other operations based on a JSON profile you
define.
PDF Checker is included free
with every PDF Optimizer purchase. Running PDF Checker before PDF Optimizer is
the right architecture for any production pipeline: you validate first, then
optimize, then archive or deliver.
Pattern 1: Simple Batch Processing
The simplest pipeline processes
a directory of PDFs on a schedule. A cron job or task scheduler triggers PDF
Checker on an input directory, passes the validated files to PDF Optimizer with
a defined JSON profile, and writes the output to a delivery or storage
directory.
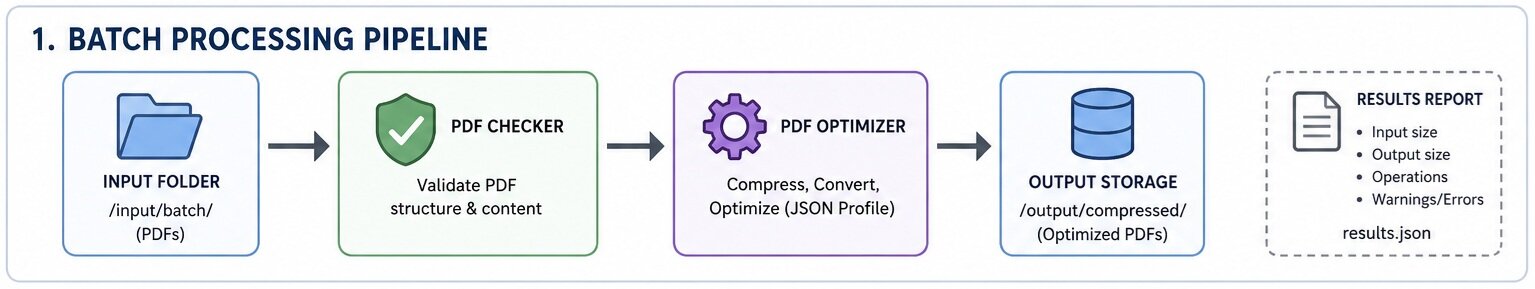
The command structure for PDF
Optimizer batch processing is straightforward. You specify the input file or
directory, the JSON profile to apply, and the output location. A typical
production command looks like this:
pdfoptimizer
-i /input/batch/ -p profiles/compressionMedium.json -o /output/compressed/ -r
results.json
The -r flag generates a results
report for every processed file, giving you a log of input size, output size,
operations applied, and any warnings or errors encountered. This report is
essential for monitoring pipeline health and auditing optimization outcomes at
scale.
For this pattern, the JSON
profile is the primary control mechanism. A medium compression profile might
downsample color images to 150 DPI, apply JPEG compression at quality 75, and
remove embedded thumbnails and JavaScript. A high compression profile might
target 96 DPI for screen-only documents with more aggressive recompression. You
define the profiles once, store them in version control, and apply them
consistently to every document in the pipeline.
Pattern 2: Event-Driven Processing
For systems where documents
arrive continuously rather than in scheduled batches, an event-driven
architecture is more appropriate. In this pattern, a do...
### PDF Optimizer vs. Ghostscript vs. Adobe Acrobat vs. iLovePDF: Comparing PDF Compression Tools
**URL:** https://www.datalogics.com/pdf-optimizer-vs-ghostscript-vs-adobe-acrobat-vs-ilovepdf-comparing-pdf-compression-tools
A structured, fair comparison of four PDF compression options commonly evaluated by developers and engineering teams. Covers compression quality, batch and CLI capability, PDF/A support, color management, licensing, and enterprise fit. Designed for developers on an evaluation sprint.
If you are evaluating PDF
compression tools for a production workflow, you are probably looking at some
combination of these four options. They are the most commonly discussed tools
in developer forums, and each has genuine strengths alongside real limitations.
This post compares them directly, without promotional framing, so you can make
a clear decision for your use case.
What This Comparison Covers
The evaluation criteria that
matter most for enterprise and developer workflows are: compression quality,
batch and command-line capability, PDF/A and compliance conversion support,
color management, licensing model, enterprise support, and data handling. Each
tool is assessed on all of these dimensions.
Ghostscript
Ghostscript is a free,
open-source PostScript and PDF interpreter that has been used for PDF
processing for decades. Its primary advantage is cost: it is free to use and
widely available on Linux, Windows, and macOS. For developers who need basic
PDF compression and have flexibility on output quality, Ghostscript is a
functional starting point.
Its limitations in enterprise
contexts are significant, however. Ghostscript compression output is
inconsistent across document types, and the compression quality at equivalent
settings is often lower than commercial alternatives. The configuration model
requires passing command-line flags, not a structured profile file, which makes
it difficult to define and reuse consistent settings across large document
batches.
The most important enterprise
concern with Ghostscript is licensing. Ghostscript is licensed under the AGPL,
which requires that any application distributing or linking to Ghostscript
release its own source code under the same license. Organizations building
proprietary software pipelines that incorporate Ghostscript may be exposing
themselves to licensing risk. A commercial Ghostscript license from Artifex is
available, but adds cost.
Ghostscript does not have native
PDF/A output support. Producing PDF/A output from Ghostscript requires
workarounds and produces inconsistent results that often fail PDF/A validators.
Color management is limited compared to purpose-built PDF optimization tools.
Adobe Acrobat
Adobe Acrobat is the most widely
recognized PDF tool in the market, and it has a legitimate place in individual
and small team workflows. For desktop use, it is capable and familiar. For
enterprise automation, it has structural limitations that make it a poor fit.
Acrobat was not designed for
server-side automation or headless batch processing. The software requires a
GUI environment to run, which creates significant complications when deploying
on cloud infrastructure or running in container-based pipelines. While Adobe
has released some APIs for certain PDF operations, there is no native CLI tool
equivalent to running Acrobat in a production backend.
Acrobat licensing is per-seat,
which means costs scale with the number of workstations or virtual machines
running the software. For workflows processing millions of documents across
distributed infrastructure, the licensing model becomes prohibitively expensive.
Acrobat does support PDF/A output and has solid color management capabilities,
but these strengths are only accessible in the context of its desktop interface
or limited API surface.
If you have ever been told that
your organization needs to produce "compliant PDFs" without being
told which standard applies, or why, you are not alone. PDF/A, PDF/X, and PDF
2.0 are three distinct standards that serve three distinct purposes. Applying
the wrong one to your workflow, or attempting to apply all three at once,
creates unnecessary complexity without improving compliance.
This post explains what each
standard actually requires, what problems each one was designed to solve, and
how to determine which one your workflow needs.
PDF/A: The Archival Standard
PDF/A is an ISO standard (ISO
19005) designed for long-term document preservation. The core requirement is
self-containment: a PDF/A document must include everything needed to render it
identically on any compliant viewer, at any point in the future, without
relying on external resources.
In practice, this means fonts
must be fully embedded, color spaces must be explicit, encryption and password
protection are prohibited, JavaScript and executable content are not allowed,
and XFA (XML Forms Architecture) forms are prohibited. The document must render
consistently regardless of the software or hardware used to view it.
PDF/A comes in several
conformance levels. PDF/A-1b is the most basic and most widely supported: it
requires visual reproducibility but does not mandate Unicode text mapping.
PDF/A-2b adds support for JPEG 2000 compression, optional content groups, and embedded
files. PDF/A-3u, which is supported by PDF Optimizer, requires Unicode
character mapping for all text and allows any file type to be embedded as an
attachment, making it the right choice for workflows where machine-readable
text extraction will be required later.
PDF/A is used in healthcare,
financial services, government, and legal environments where documents must be
retained for years or decades and reproduced reliably without dependency on any
particular software version. If your compliance requirement is long-term
retention, PDF/A is typically the standard required for long-term retention
workflows.
PDF/X: The Print Exchange Standard
PDF/X is an ISO standard (ISO
15930) designed for the reliable exchange of print-ready files between content
creators and print production environments. Where PDF/A is about future
readability, PDF/X is about present-tense production accuracy.
PDF/X requirements focus on
color precision and rendering predictability. Transparency must be flattened,
because many prepress raster image processors cannot handle live transparency.
All fonts must be embedded. Color spaces must be defined in a way that ensures
consistent reproduction on the target output device. External content and
references are not permitted.
PDF/X is used in commercial
printing, packaging production, magazine and catalog publishing, and any
workflow where a PDF is being handed off to a press or service bureau. If your
requirement is print accuracy rather than archival retention, PDF/X is the
standard that applies.
Note that PDF/A and PDF/X can
coexist in the same document in certain combinations, most commonly PDF/A-1b
and PDF/X-1a, but this is unusual outside of publishing workflows that require
both archival storage and print production.
PDF 2.0: The Current Specification